I loved Encarta

That happened long before Wikipedia. I loved Encarta. Well, before Encarta, I used to read this thing a lot:

But then Encarta arrived and I loved it. It did fit into single CD and didn’t take too much space on disk. I could look up all these articles in it, without having to use expensive dialup, fast. I remember my school buddies coming over and watching those tiny movies in it. I could rip it off for my school works, and look incredibly smart (now people rip off Wikipedia and don’t get too much credit for that :).

It is dead.

People on the interwebs suggest that employees at Wikipedia and Encyclopaedia Britannica will be throwing parties tonight. Oh well, Wikipedia is already up to date about this. Every encyclopedia out there was an inspiration for Wikipedia, more so than any technology or “web-two-oh” hype. There’s not much joy seeing good things die.

Ten years ago I imagined, that once I have my own home, I’ll have a place to put a full set of dead-tree Britannica, like my parents had “Lithuanian soviet encyclopaedia”. Wikipedia changed my plans (now there’re two flat panels staring at Wiki, inside and outside), but it seems it already is changing the world around it way more. RIP Encarta. You were inspiring, and really too young to die. If it was us, we didn’t mean it, really. By the way, that content of yours, I’d be glad to see it free. *wink*
I'm a creative commoner

Lately Creative Commons is becoming very dominant topic in my life. First of all, I see all the people in free culture world holding their breath and waiting for Wikipedia switch to CC license. I’m waiting for that too – and personally I really endorse it. Though usually people do not really notice licenses on web content, they really do once they see something they really want to reuse. Wikipedia ends up being isolated island, if it doesn’t go after sharing and exchanging information with other projects.

It takes time to understand one is ‘creative commoner’. I do have a t-shirt with such caption, but it is much more comfortable once you start feeling real power of use and reuse of information. Few anecdotes…
Continue reading “I'm a creative commoner”

twitter!

Quite often fast databases, super-duper backend caching layers and other fancy stuff doesn’t help if you don’t serve your customer right. Take, for example, Twitter. This service has lots and lots of clicks, people following each other, in endless loops, trees, and probably serving occasional page-views.

I noticed that every click seemed to be somewhat sluggish, and started looking at it (sometimes this gets me free lunch or so ;-)

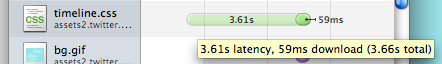
Indeed, every click seemed to reload quite a bit of static content (like CSS and JavaScript from their ‘assets’ service). Every pageview carrying information took 2s to serve, but static content slowed down the actual page presentation for three-six additional seconds.


Now, I can’t say Twitter didn’t try to optimize this. Their images are loaded from S3 and have decent caching (even though datacenter is far away from Europe), but something they completely control and own, and what should make least amount of costs, ends up the major slow-down.

What did they do right? They put timestamp markers into URLs for all included javascript and stylesheet files, so it is really easy to switch to new files (as those URLs are all dynamically generated by their application for every pageview).

What did they do wrong? Let’s look at the response headers for the slow content:

Accept-Ranges:bytes
Cache-Control:max-age=315360000
Connection:close
Content-Encoding:gzip
Content-Length:2385
Content-Type:text/css
Date:Wed, 25 Mar 2009 21:12:21 GMT
Expires:Sat, 23 Mar 2019 21:12:21 GMT
Last-Modified:Tue, 24 Mar 2009 21:21:04 GMT
Server:Apache
Vary:Accept-Encoding

It probably looks perfectly valid (expires in ten years, cache control existing), but…

  • Cache-Control simply forgot to say this is “public” data.
  • ETag header could help too, especially if no ‘public’ is specified.
  • Update: Different pages have different timestamp values for included files – so all caching headers don’t have much purpose ;-)

And of course, if those files were any closer to Europe (now they seem to go long long way to San Jose, California), I’d forgive lack of keep-alive. Just serve those few files off a CDN, dammit.

Linux 2.6.29

2.6.29 was released. I don’t usually write about linux kernel releases, thats what Slashdot is for :), but this one introduces write barriers in LVM, as well as ext4 with write barriers enabled by default. If you run this kernel and forget to turn off barrier support at filesystems (like XFS, nobarrier), you will see nasty performance slowdowns (recent post about it). Beware.

MySQL at Debian and Ubuntu

Good news, mysql-server package doesn’t suck miserably on Debian 5.0 or Ubuntu 8.10, unlike previous versions did (there were quite a few rants about CHECK TABLES being ran on huge healthy InnoDB tables, mysqld_safe would suddenly use 100% CPU, binlogs would be placed on /var/run/ and cleaned up on restart, etc).

Now, Ubuntu provides you with AppArmor (my new favorite security thing :) profile that doesn’t suck either, and Debian is a bit rude:
There is ‘tasksel’ tool, which allows you to install groups of packages. Debian has a task ‘Database server’ which will install PostgreSQL. Ubuntu is more politically correct and has renamed that task to “PostgreSQL server”.

MySQL has to do quite some work to repair its image in OS-engineer-geek mindsets, these people tend to love PG more, and once project is community-led, most active participants win the decisive power.

Quite important to look at versions – Ubuntu Intrepid carries 5.0.67, and Debian carries 5.0.51. As I’m way more exposed to everyday issues within MySQL, I value distributions that don’t just backport security fixes, but use MySQL bugfix releases way more proactively. The difference between those two versions has a nearly full year of performance, stability and feature maturity work (and thats really LOTS of real hard intensive work by my teammates). Debian will probably stay at that exact version, unless one uses ‘testing’ or ‘unstable’ packages – so over time the gap will just widen.

Oh, and why I ended up writing this today – Ubuntu/Canonical people were really nice and open, and tried to get as much as possible of feedback to make MySQL shine on their distribution. Gotta say, they’re already leading :)

Pictures! Trips!

Apparently I didn’t take too many pictures in 2008, but today I did upload quite a few to my flickr photostream. Though last year I traveled more than ever (though at least 6 trips were to SF area… ;-), I even left my handycam at home few times.

Still, there was vacation in Greece, Wikimania, which was mostly looping between library of Alexandria and hotel, and layover in Kiev (that was best (shortest/cheapest, not most comfortable) route to Cairo).

RESET SLAVE, bash edition

Nearly every job advertisement for MySQL DBA positions asks for ‘shell scripting’, so I decided to investigate what it is. I remembered some performance training, where I was told how forking is bad, and one should attempt to use shell features as much as possible (like, avoid paths to something, what can be used by builtin (e.g. don’t use /usr/bin/[, just pure [ instead )

I tried to automate one MySQL DBA task (reinitializing slave after relay log corruption or after copying in cloned dataset from other server) using just bash – and it kind of worked. From now on I can put ‘Shell scripting’ proudly on my resume :-)

Next step – learn JCL (some people think this is funny :)

What was your most complicated task solved with shell scripts? :)

#!/bin/bash

HOST=$1
RPASS=$(<passwordfile)

IFS="
"

mysql -h $HOST -e "STOP SLAVE"

for line in $(mysql -e "SHOW SLAVE STATUS" -E -h $HOST)
 do
	key=${line%:*}  # Split off what goes before :
	key=${key// }   # And trim spaces
	data=${line#*:} # Split off what goes after :
	data=${data// } # And trim spaces yet again!!!

	case $key in
		Exec_master_log_pos) LOGPOS=$data;;
		Relay_Master_Log_File) LOGFILE=$data;;
		Master_Host) RHOST=$data;;
		Master_User) RUSER=$data;;
	esac

 done

if [ -z $LOGPOS -o -z $LOGFILE ]; then
        echo "OMG FAIL NO POSITIONS KNOWN"; exit;
fi

mysql -f -h $HOST -e "
        RESET SLAVE;
        CHANGE MASTER TO
                MASTER_HOST='$RHOST',
                MASTER_USER='$RUSER',
                MASTER_PASSWORD='$RPASS',
                MASTER_LOG_FILE='$LOGFILE',
                MASTER_LOG_POS=$LOGPOS ;
        START SLAVE
        "

Update: rewrote the last ‘mysql’ command to avoid multiple unnecessary forks! (thanks, Aidai :)

stupid dtrace trick

So, if there is no way to flush status variables of a server, one could use dtrace (and run SHOW GLOBAL STATUS ;-)

#!/usr/sbin/dtrace -Fws
int *zero;
BEGIN { zero=alloca(4); *zero=0; }
pid$target:mysqld:add_to_status*:1b {
        copyout(zero,uregs[R_ECX],4);
        copyout(zero,uregs[R_EDX],4);
}

P.S. This is just simple proof of concept, that can warp counters back, ignore some variables, and eat babies. Code position and registers are architecture, version and build dependent.
P.P.S. I’m giving dtrace talk at mysql conference as well (yay plugs ;-)

stupid innodb tricks

When it comes to extreme tuning, this is how I got +5% performance in one of my tests on 8-cpu machine (contended at mtr_commit()):

gdb -p $(pidof mysqld) -ex "set srv_spin_wait_delay=50" -batch

P.S. was probably worth posting this just to point out that there’re ways to fill the gap between recompile and my.cnf settings :)